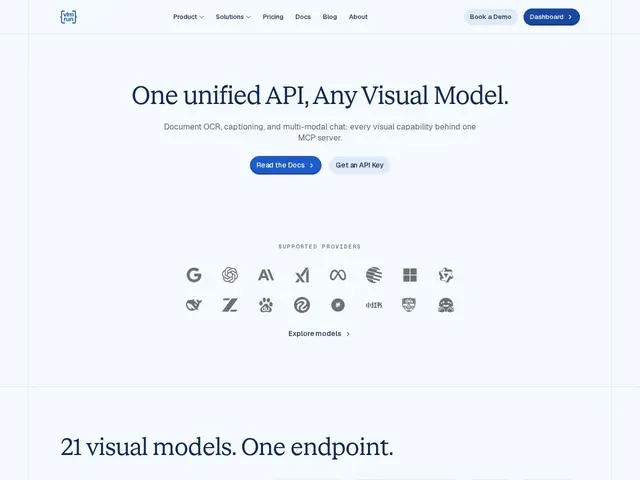
One OpenAI-compatible API that routes to 21 vision-language models for OCR, image, video and multimodal chat
vlmrun.com
44 tools curated in this category — including VLM Run Gateway, Compute.cheap, Slotstream
techFind on mySelectas all sites and tools related to model-hosting. This selection of 44 resources is reviewed and maintained by the community. The most popular include VLM Run Gateway, Compute.cheap, Slotstream. Each tool comes with a review, tags, comparisons and alternatives to help you make the best choice.
One OpenAI-compatible API that routes to 21 vision-language models for OCR, image, video and multimodal chat
A GPU compute marketplace offering NVIDIA H100 and H200 GPUs at cost-optimized rates, with both on-demand and spot pricing for AI training and inference workloads.
A Swift-based inference engine that enables running the 125-billion parameter Qwen 3.8-Flash-Next model on Apple Silicon Macs with limited memory by streaming expert weights from storage. Achieves approximately 12 tokens/second on 48GB M-series Macs.
Self-hosted AI platform for distributed, multi-model LLM inference on Kubernetes clusters with single-command installation and air-gapped deployment support.
A free command-line tool that tells you which local AI models your computer can actually run — before you spend an hour downloading one that just crashes or crawls.
A single API that gives developers access to 100+ AI models for video, image, audio and chat, instead of integrating each vendor separately.
A free, open-source Mac app that runs AI chatbots and agents entirely on your own computer, with nothing ever sent to the cloud.
Open-source on-device AI runtime that runs LLMs, vision models and speech models directly on phones, laptops and wearables — no cloud round-trip required.
An AI inference API built specifically for speed — over 1,000 image, video, audio and language models served through one endpoint with sub-1-second latency and no cold starts.
A control panel for getting AI models and agents from a developer's laptop into real production use — deployment, scaling, and governance — built to run on whichever cloud a company already uses instead of locking them into one.
A single API endpoint that talks to 600+ AI models from 30+ providers, so switching from one AI model to another — or spreading requests across several for cost or reliability — doesn't mean rewriting your app's code.
A safety checker for AI systems that catches hallucinations, unsafe answers and factual mistakes before they reach a user, using its own purpose-built judge models instead of relying on a general-purpose LLM to grade itself.
A European, publicly-traded cloud built specifically for AI workloads — GPU clusters, training, inference — for companies that want serious AI compute without depending on a US hyperscaler.
A marketplace of ready-to-call AI models for generating images, video, audio and 3D content — like an app store of generative AI models you access through a single API instead of hosting each model yourself.
Pay-by-the-second GPU cloud for training and running AI models, with no contracts and fast serverless cold starts.
GPU cloud built for AI research and production, scaling from a single rented GPU up to superclusters with over 165,000 GPUs.
Enterprise cloud built specifically around NVIDIA GPUs, providing large-scale compute for training and running the biggest AI models.
Cloud inference platform for running and fine-tuning open-source language models fast, without owning any GPUs.
Serverless cloud platform that runs Python code, including AI model training and inference, on GPUs with sub-second startup and pay-per-second billing.
Managed feature store and AI lakehouse platform for building production machine-learning systems with millisecond-latency feature serving.