WaveSpeedAI
An AI inference API built specifically for speed — over 1,000 image, video, audio and language models served through one endpoint with sub-1-second latency and no cold starts.
🔗 Visit WaveSpeedAI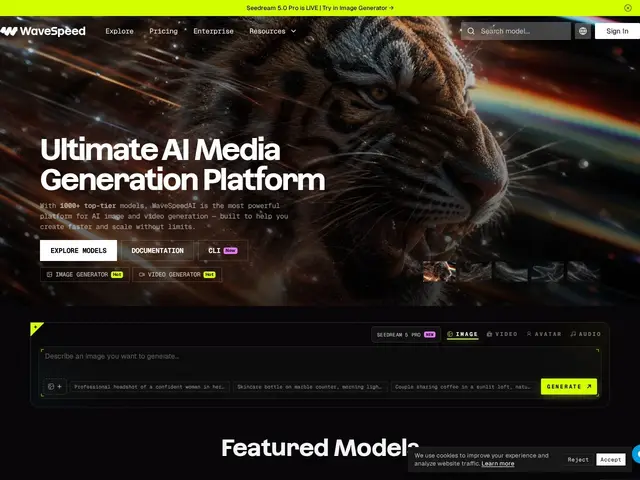
Description
Even when a developer picks a good AI model, calling it can feel sluggish — the server has to 'wake up' before it responds, sometimes taking many seconds. WaveSpeedAI is built to fix exactly that: it hosts a large catalog of AI models behind one API and specifically engineers for near-instant responses, so an app calling it doesn't make users stare at a loading spinner while a model spins up.
WaveSpeedAI is a unified inference platform offering pay-per-use access to 1,000+ AI models — image and video generation, LLMs, audio — through a single API, with a stated focus on sub-1-second latency and zero cold starts. Pricing is fully usage-based with no monthly commitment: images run roughly $0.005-$0.008 each, video $0.01-$0.15 per second depending on model, and LLM access is billed per million tokens (for example, Claude Opus around $5/$25 per million input/output tokens, DeepSeek around $1.84/$3.66). A four-tier volume program (Bronze, Silver, Gold, Ultra) applies discounts as monthly spend grows, and new accounts get a $1 credit with no card required.
💬 Our review
The short version: WaveSpeedAI competes on one clear axis — speed — and backs that up with a real open-source footprint (its Go-based 'waverless' inference runtime has over 600 GitHub stars), which is a healthier signal than a marketing claim alone.
The catch is that WaveSpeedAI is a newer, smaller player (founded 2025) going up against fal and Replicate, both of which have longer track records and broader ecosystems; the latency advantage is real on paper but worth testing on your own workload before switching, since 'sub-1-second' claims vary a lot by model and payload size in practice. Pricing is competitive and the per-million-token LLM rates are transparent and easy to compare against direct provider pricing. For teams whose bottleneck is genuinely inference latency — real-time or interactive AI features where every second matters — WaveSpeedAI's speed-first positioning is worth evaluating directly; for everything else, the broader catalogs at fal or Replicate may be the safer default given their maturity.
💰 Pricing
📊 Global score
🤖 AI-enriched data
Pay-per-use, aucun engagement mensuel. $1 de crédit gratuit sans CB. Images $0.005-$0.008/image. Vidéo $0.01-$0.15/sec. LLM facturés au million de tokens (ex. Claude Opus $5/$25 M input/output). 4 paliers volume (Bronze/Silver/Gold/Ultra) avec remises.
Pros
Positionnement clair sur la latence (<1s annoncée, zéro cold start)
Empreinte open source réelle (waverless, 600+ stars) au-delà du seul marketing
Tarification par million de tokens transparente et facile à comparer
Cons
Acteur récent (2025) face à des concurrents plus établis (fal, Replicate)
Les claims de latence méritent d'être testés sur son propre cas d'usage
Financement non communiqué publiquement