The most widely used open-source tool for writing data quality checks in Python — you define what your data should look like as code, and it validates every pipeline run against those expectations automatically.
greatexpectations.io
If you want to fine-tune a small language model on your own documentation, the hard part usually isn't the training — it's turning messy PDFs, markdown files, and code comments into clean question-answer pairs a model can actually learn from, without either hallucinating answers or copying garbage formatting into the dataset. dataset-cleaner-cli automates that grunt work: point it at your docs, it uses a locally-running model to generate Q&A pairs, then checks each one for accuracy before it goes in the final dataset. dataset-cleaner-cli is a Python (3.10+) command-line tool that extracts question-answer datasets from technical documentation — PDF, Markdown, TXT, CSV, EPUB, and MOBI — using a local LLM via Ollama, so no data leaves your machine and no API key is required. The pipeline parses and chunks the source documents, generates Q&A pairs locally, then validates them semantically with sentence-transformers and runs hallucination detection to filter out answers not actually supported by the source text. It uses Python's AST module to validate any code snippets it captures, and can resolve dynamic markup from FastAPI, Jinja, and MkDocs. Output formats include ShareGPT, Alpaca, OpenAI Messages, and plain text completions — the standard formats most fine-tuning pipelines expect. It's AGPL-3.0 licensed and still early-stage (5 commits as of August 2026).
| # | Tool | Best for | Price |
|---|---|---|---|
| 1 | Data engineers et analytics engineers utilisant Python, Jupyter et orchestrateurs de données | — | |
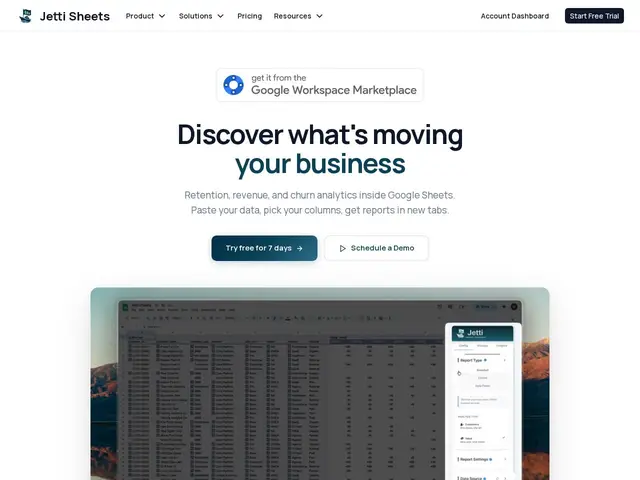
| 2 | Équipes SaaS Product/Revenue en petite et mid-market cherchant l'analytique de cohortes et churn sans BI complexe | — | |
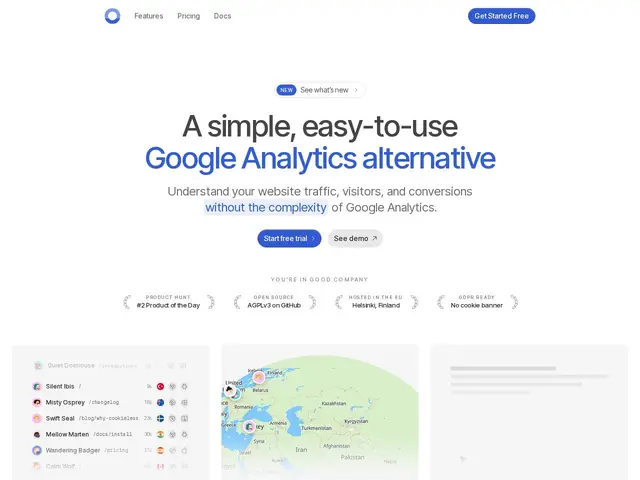
| 3 | Website owners and teams wanting cookieless analytics with revenue insight | — | |
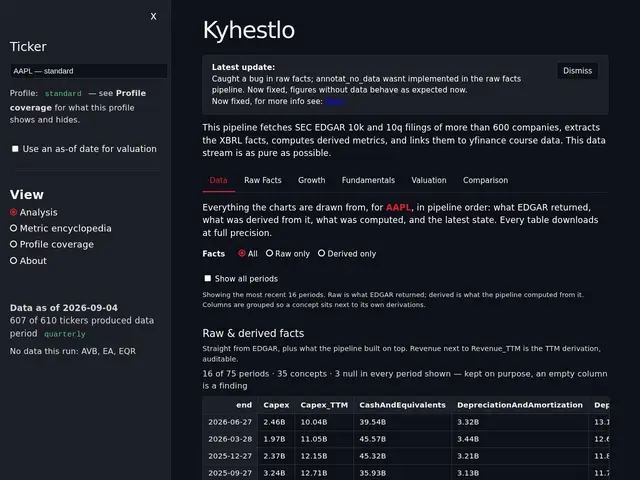
| 4 | Financial analysts and quantitative researchers needing SEC XBRL fundamentals | — | |
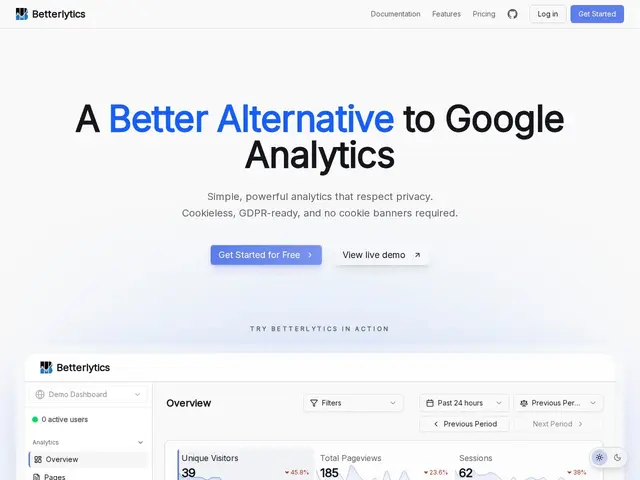
| 5 | Website owners and teams wanting privacy-first analytics with session replay and uptime monitoring | — | |
| 6 | Développeurs voulant présenter leur portfolio GitHub de façon originale, ou trouver des issues open-source abordables | — | |
| 7 | Développeurs construisant des pipelines de capture de données sans infra lourde | — | |
| 8 | Équipes data et ingénierie nécessitant souveraineté des données et contrôle d'infrastructure | — | |
| 9 | Data engineers, analystes, praticiens ML voulant prototyper des pipelines rapidement | — | |
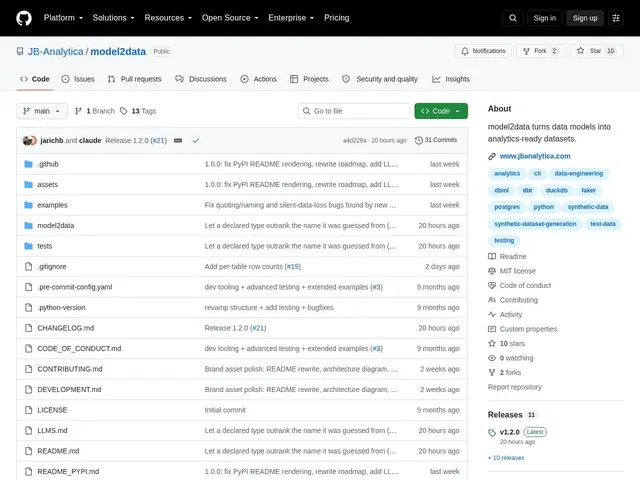
| 10 | Analytics engineers et équipes data utilisant dbt, ayant besoin de données de test réalistes sans accès aux données de production | — | |
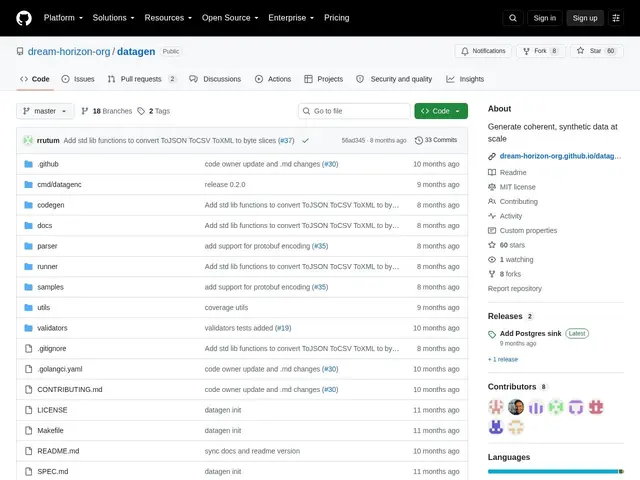
| 11 | Développeurs et ingénieurs data ayant besoin de générer de gros volumes de données de test cohérentes | — | |
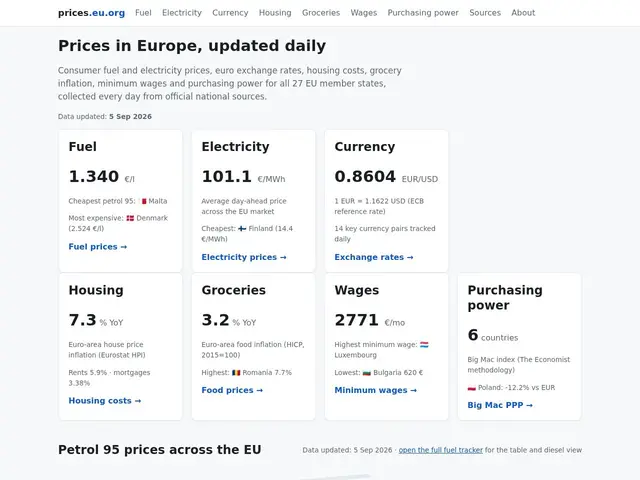
| 12 | Consommateurs européens, chercheurs et journalistes suivant les comparaisons de prix et indicateurs économiques dans l'UE | — |
The most widely used open-source tool for writing data quality checks in Python — you define what your data should look like as code, and it validates every pipeline run against those expectations automatically.
Turns the customer and revenue data already sitting in your Google Sheets into churn, retention and cohort analytics in seconds, no formulas or BI tool required.
Cookieless, privacy-first web analytics with an AI chat interface — a paid, open-source alternative to Google Analytics.
Extracts standardized S&P 500 fundamental financial data directly from SEC XBRL filings for financial analysis.
Privacy-first, cookieless web analytics with session replay, error tracking, and uptime monitoring, open-source and self-hostable.
Turns your GitHub repositories into a walkable 3D town — stars and forks become building height and width — so you can explore a portfolio, or find beginner-friendly open-source issues, as a game instead of a list.
Python library that captures streaming data durably into Iceberg tables with no broker, daemon, or catalog service to run.
Open-source ETL platform that builds data pipelines visually or in code and runs them on DuckDB, with no vendor lock-in.
Open-source visual builder for data and ML pipelines that lets you preview each transformation live and export clean pandas/Polars Python code.
A command-line tool that reads a database schema and generates a full, realistic fake dataset plus a ready-to-run dbt project — no production data or manual scaffolding needed.
A synthetic data generator that lets you describe your data model in a simple language, then compiles it into fast native code to produce large, coherent test datasets.
A free daily dashboard comparing fuel, electricity, groceries, wages, and other cost-of-living numbers across all 27 EU countries.