Databricks
docs.databricks.com
Running large-scale data queries and ETL jobs on CPUs is the default in most data warehouses, but it's also slow and expensive at scale — the same reason gaming and AI moved to GPUs years ago. ParaQuery brings that same GPU acceleration to everyday Spark and SQL data processing, without asking you to move your data anywhere or rewrite your pipelines: it plugs into data you already have in BigQuery, Snowflake, or Redshift and runs the same queries faster. Technically, ParaQuery is a fully-managed, Spark-compatible platform that claims roughly double the performance at about half the cost compared to standard CPU-based processing on those warehouses, works across GCP, AWS, and Azure, requires no data ingestion or migration, and avoids vendor lock-in since your data stays where it already lives. It's aimed at data teams running meaningful ETL or query volume on major cloud data warehouses who are looking to cut both compute time and cloud spend. Pricing is enterprise/custom, with the company offering risk-free pilots and a custom ROI analysis before you commit — no public self-serve pricing is available. It's Y Combinator-backed and also supported by Google for Startups, AWS, Microsoft, and NVIDIA's startup programs, which lends some technical credibility given the GPU-acceleration angle.
| # | Tool | Best for | Price |
|---|---|---|---|
| 1 | Développeurs | — | |
| 2 | Développeurs | — | |
| 3 | Professionnels de l'informatique | — | |
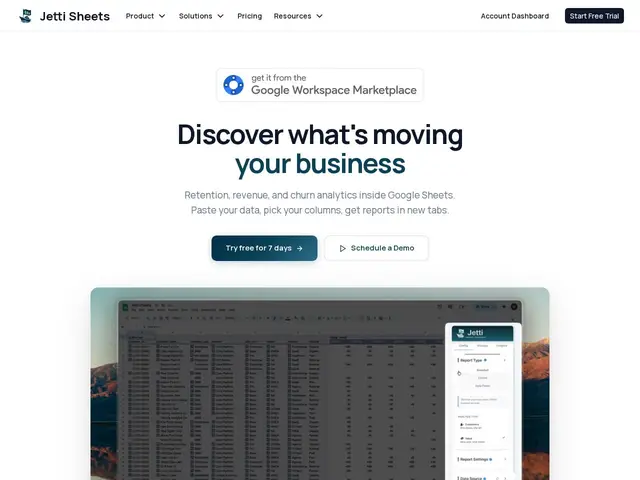
| 4 | Équipes SaaS Product/Revenue en petite et mid-market cherchant l'analytique de cohortes et churn sans BI complexe | — | |
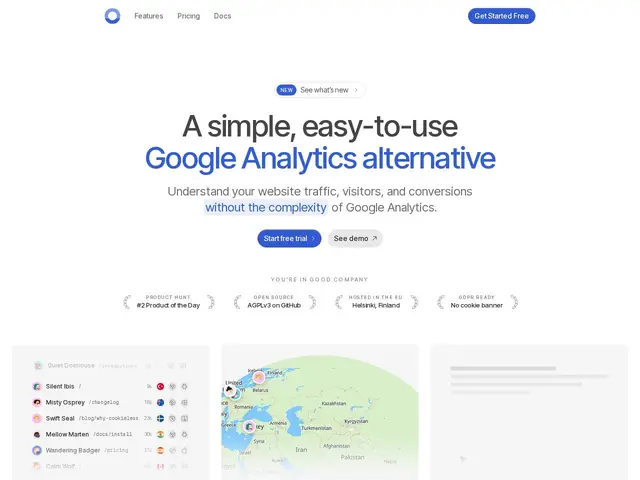
| 5 | Website owners and teams wanting cookieless analytics with revenue insight | — | |
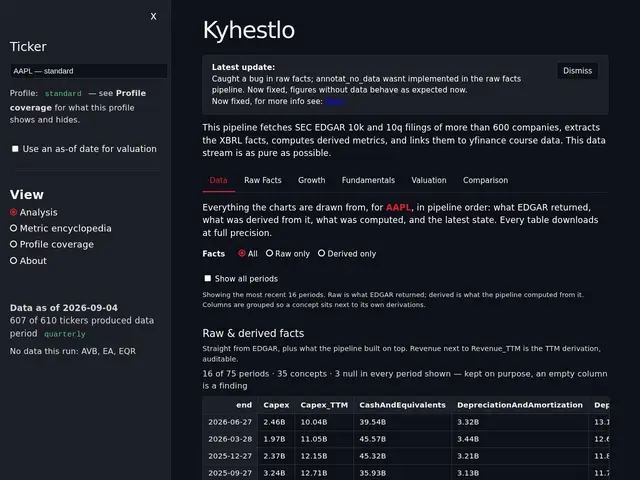
| 6 | Financial analysts and quantitative researchers needing SEC XBRL fundamentals | — | |
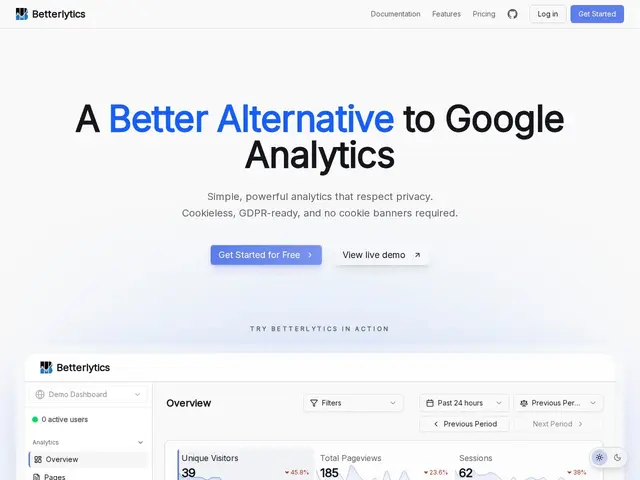
| 7 | Website owners and teams wanting privacy-first analytics with session replay and uptime monitoring | — | |
| 8 | Développeurs voulant présenter leur portfolio GitHub de façon originale, ou trouver des issues open-source abordables | — | |
| 9 | Développeurs construisant des pipelines de capture de données sans infra lourde | — | |
| 10 | Équipes data et ingénierie nécessitant souveraineté des données et contrôle d'infrastructure | — | |
| 11 | Data engineers, analystes, praticiens ML voulant prototyper des pipelines rapidement | — | |
| 12 | Analytics engineers et équipes data utilisant dbt, ayant besoin de données de test réalistes sans accès aux données de production | — |
Turns the customer and revenue data already sitting in your Google Sheets into churn, retention and cohort analytics in seconds, no formulas or BI tool required.
Cookieless, privacy-first web analytics with an AI chat interface — a paid, open-source alternative to Google Analytics.
Extracts standardized S&P 500 fundamental financial data directly from SEC XBRL filings for financial analysis.
Privacy-first, cookieless web analytics with session replay, error tracking, and uptime monitoring, open-source and self-hostable.
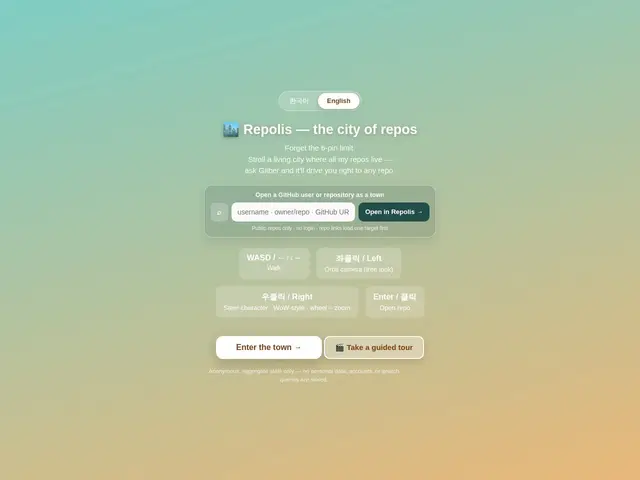
Turns your GitHub repositories into a walkable 3D town — stars and forks become building height and width — so you can explore a portfolio, or find beginner-friendly open-source issues, as a game instead of a list.
Python library that captures streaming data durably into Iceberg tables with no broker, daemon, or catalog service to run.
Open-source ETL platform that builds data pipelines visually or in code and runs them on DuckDB, with no vendor lock-in.
Open-source visual builder for data and ML pipelines that lets you preview each transformation live and export clean pandas/Polars Python code.
A command-line tool that reads a database schema and generates a full, realistic fake dataset plus a ready-to-run dbt project — no production data or manual scaffolding needed.