A modern responsive front-end framework based on Material Design.
materializecss.com
Real-time data pipelines have a reputation for being one of the more painful corners of software engineering — usually because the standard tools (Kafka Streams, Apache Flink, Spark Streaming) assume you're willing to run and tune a whole cluster just to compute a rolling average. SQLFlow is built for the much more common case: you have one stream of events and you want to aggregate it, and you'd rather write a SQL query than provision a JVM cluster to do it. SQLFlow runs as a single-node, single-process engine built on DuckDB and Apache Arrow, consuming from Kafka or WebSockets, transforming with plain SQL (aggregations, windowing), and writing results to PostgreSQL, Kafka, or cloud storage in Parquet/Iceberg format. In benchmarks the Go-rewritten version claims 927,000 messages/second Kafka-to-sink throughput while staying within a 240 MiB memory footprint — numbers aimed squarely at people who don't want the operational overhead of a distributed streaming cluster. It's MIT-licensed, Docker-deployable, and built by Turbolytics, which also offers optional paid consulting for architecture reviews and pipeline migrations on top of the free open-source core.
| # | Tool | Best for | Price |
|---|---|---|---|
| 1 | Développeurs | — | |
| 2 | Professionnels de l'informatique | — | |
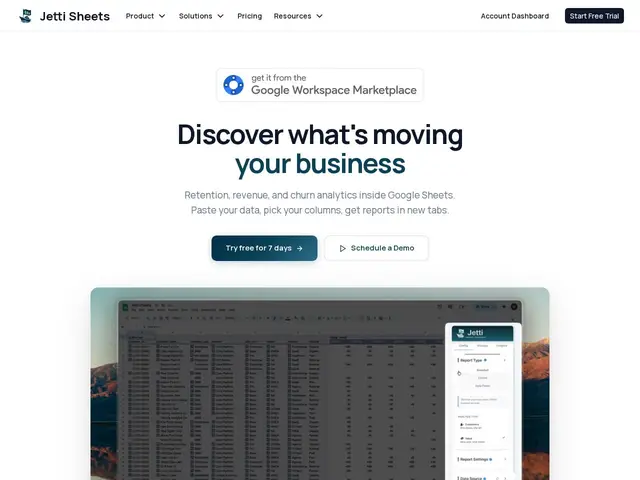
| 3 | Équipes SaaS Product/Revenue en petite et mid-market cherchant l'analytique de cohortes et churn sans BI complexe | — | |
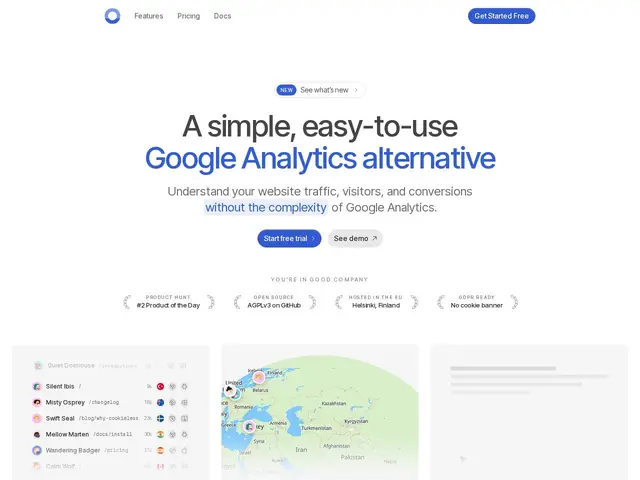
| 4 | Website owners and teams wanting cookieless analytics with revenue insight | — | |
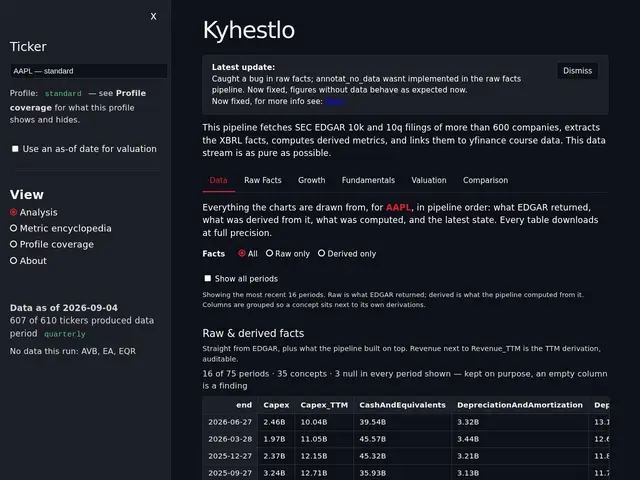
| 5 | Financial analysts and quantitative researchers needing SEC XBRL fundamentals | — | |
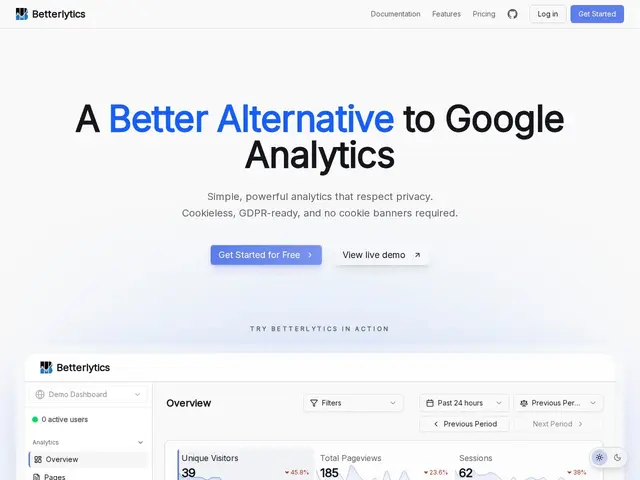
| 6 | Website owners and teams wanting privacy-first analytics with session replay and uptime monitoring | — | |
| 7 | Développeurs voulant présenter leur portfolio GitHub de façon originale, ou trouver des issues open-source abordables | — | |
| 8 | Développeurs construisant des pipelines de capture de données sans infra lourde | — | |
| 9 | Équipes data et ingénierie nécessitant souveraineté des données et contrôle d'infrastructure | — | |
| 10 | Data engineers, analystes, praticiens ML voulant prototyper des pipelines rapidement | — | |
| 11 | Analytics engineers et équipes data utilisant dbt, ayant besoin de données de test réalistes sans accès aux données de production | — | |
| 12 | Développeurs et ingénieurs data ayant besoin de générer de gros volumes de données de test cohérentes | — |
Turns the customer and revenue data already sitting in your Google Sheets into churn, retention and cohort analytics in seconds, no formulas or BI tool required.
Cookieless, privacy-first web analytics with an AI chat interface — a paid, open-source alternative to Google Analytics.
Extracts standardized S&P 500 fundamental financial data directly from SEC XBRL filings for financial analysis.
Privacy-first, cookieless web analytics with session replay, error tracking, and uptime monitoring, open-source and self-hostable.
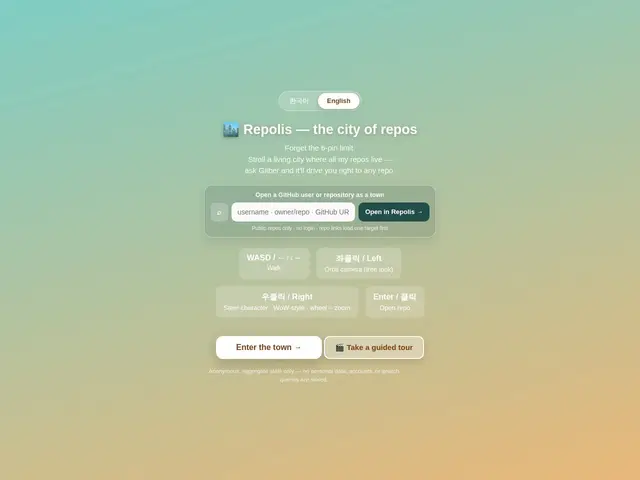
Turns your GitHub repositories into a walkable 3D town — stars and forks become building height and width — so you can explore a portfolio, or find beginner-friendly open-source issues, as a game instead of a list.
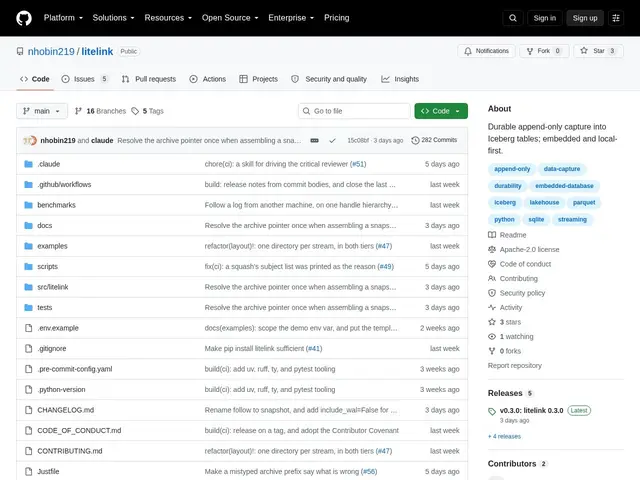
Python library that captures streaming data durably into Iceberg tables with no broker, daemon, or catalog service to run.
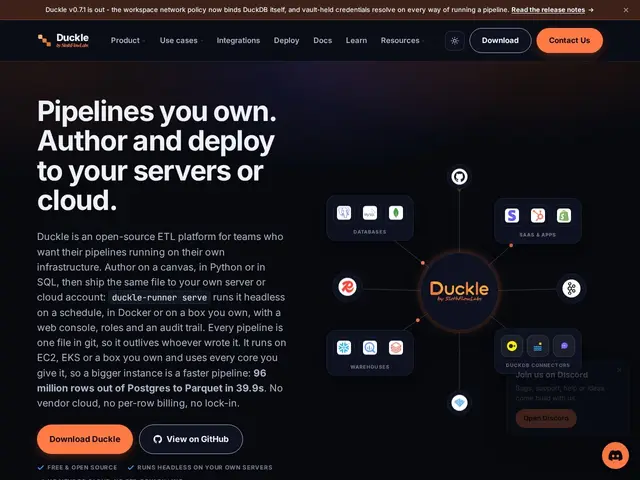
Open-source ETL platform that builds data pipelines visually or in code and runs them on DuckDB, with no vendor lock-in.
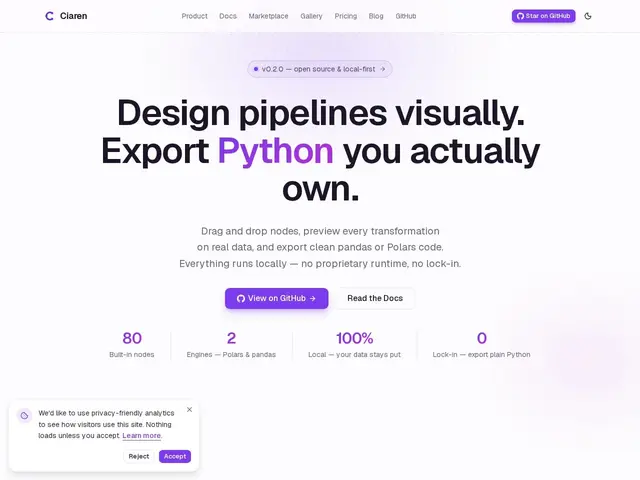
Open-source visual builder for data and ML pipelines that lets you preview each transformation live and export clean pandas/Polars Python code.
A command-line tool that reads a database schema and generates a full, realistic fake dataset plus a ready-to-run dbt project — no production data or manual scaffolding needed.
A synthetic data generator that lets you describe your data model in a simple language, then compiles it into fast native code to produce large, coherent test datasets.