Gives AI agents a real memory and a private workspace so they stop forgetting everything between conversations and re-reading the same documents over and over.
exabase.io
11 tools curated in this category — including Exabase, Engram, NestedRAG
techFind on mySelectas all sites and tools related to embeddings. This selection of 11 resources is reviewed and maintained by the community. The most popular include Exabase, Engram, NestedRAG. Each tool comes with a review, tags, comparisons and alternatives to help you make the best choice.
Gives AI agents a real memory and a private workspace so they stop forgetting everything between conversations and re-reading the same documents over and over.
Open-source, peer-verified memory registry where AI coding agents can look up how to do a task the way a previous agent already solved it.
An open-source RAG library that organizes documents into a nested tree instead of flat chunks, so an AI assistant retrieves one relevant piece per branch instead of repeating itself.
Claude Code plugin that gives sessions persistent, semantically searchable memory across conversations
A shared memory layer your AI models connect to over MCP — it remembers decisions and sources across conversations, and actively rejects about 80% of low-value information rather than storing everything.
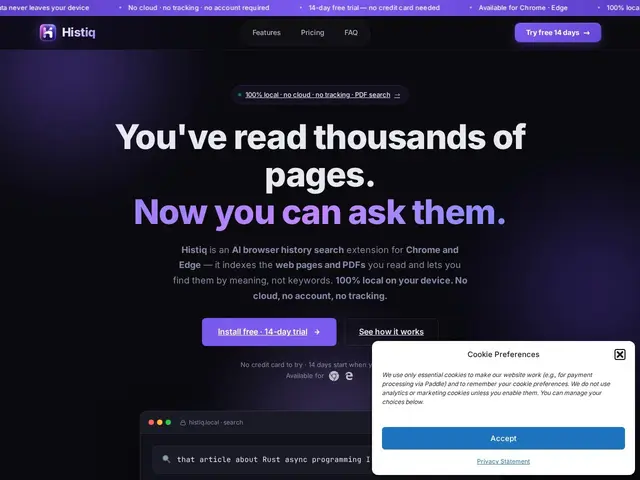
Histiq is a browser extension that lets you search your browsing history and saved PDFs using natural language, powered by local AI embeddings that never leave your device.
Lets you search inside videos using plain English — like "find the scene where someone signs a contract" — instead of scrubbing through hours of footage or relying on manual tags someone forgot to add.
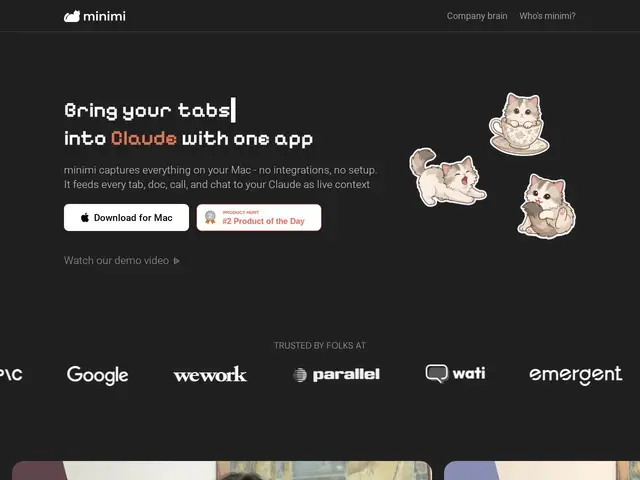
A quiet memory that watches what you're doing on your Mac so you don't have to explain it to Claude every time — your open tabs, documents, and calls become context Claude already knows, without ever leaving your computer.
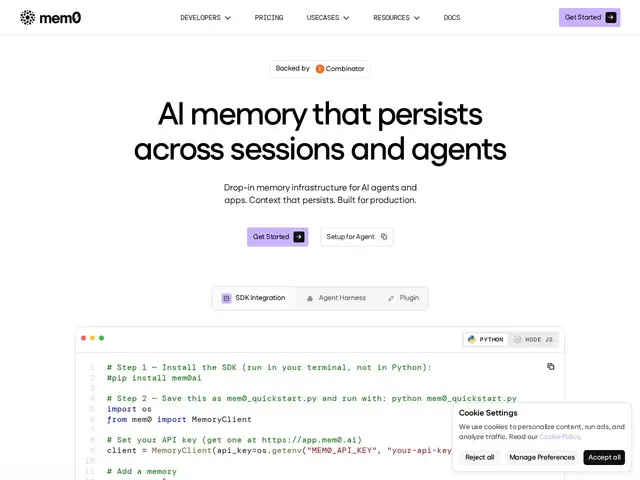
Gives AI chatbots and agents a real memory — so they remember what you told them last week — instead of forgetting everything the moment a conversation ends, the way most AI apps do by default.
Builds a living map of everything a user has told an AI agent over time — and how those facts connect and change — so the agent can pull up exactly the right context in under 200 milliseconds instead of re-reading an entire chat history.
Vector + full-text search database built on object storage: cheap at scale, sub-10ms latency, used by Cursor, Notion and Linear.